Hardware Engineering
Electronics Manufacturing
Report

For years, the Jetson family has had a gap in the middle. Orin NX gives you solid embedded compute, enough for classical machine vision or moderate multi-model inference, but it runs out of memory long before you're doing serious humanoid robotics workloads. T5000, on the other end, is a genuine step-change in what's possible on-device. But the bill of materials, the thermal envelope, and the per-unit cost are sized for high-end platforms, where those costs are absorbed by the business economics of complex use cases.
For the majority of humanoid robotics and smart-spaces projects we work on, neither extreme is the right fit. Orin NX (even with 16 GB shared memory) becomes the bottleneck as models grow. T5000 pushes hardware cost and cooling requirements out of reach for anything approaching scale production. What most projects actually need is the middle: enough current-generation compute to run modern vision-language-action (VLA) models and multi-modal robotics stacks, without paying for headroom that will sit unused in the field.
That's where T2000 and T3000 come in, and why we think they'll shift the robotics platform landscape more than the T5000 launch itself did.
|
Spec |
Orin NX 16GB |
T2000 |
T3000 |
T4000 |
T5000 |
|
Compute |
157 TOPS (INT8, sparse) |
400 TFLOPS (FP4) |
865 TFLOPS (FP4) |
1200 TFLOPS (FP4) |
2070 TFLOPS (FP4) |
|
GPU |
Ampere, 1024 CUDA cores |
Blackwell, 1024 CUDA cores |
Blackwell, 1536 CUDA cores |
Blackwell, 1536 CUDA cores |
Blackwell, 2560 CUDA cores |
|
CPU |
8-core Cortex-A78AE |
6-core Neoverse |
8-core Neoverse |
12-core Neoverse |
14-core Neoverse |
|
Memory |
16 GB LPDDR5 |
16 GB LPDDR5 |
32 GB LPDDR5 |
64 GB LPDDR5 |
128 GB LPDDR5 |
|
Memory bandwidth |
102 GB/s |
137 GB/s |
273 GB/s |
273 GB/s |
273 GB/s |
|
Power |
10–40 W |
40 W |
70 W |
70 W |
120 W |
Two details in that table are worth pausing on, because they change the answer for a lot of projects:
T3000 has the same memory bandwidth as T5000 (273 GB/s). That's easy to overlook when comparing modules by headline compute, but for memory-bound inference workloads (which is most of what runs on-device today), bandwidth is what actually determines real-world throughput. If your workload is bandwidth-limited rather than compute-limited, T3000 delivers surprisingly close to T5000 for a fraction of the cost, half the power, and none of the flagship cooling requirements.
T5000's real differentiator is RAM capacity, not raw compute. 128 GB is 4× the memory of T3000 and 8× the memory of T2000. That capacity matters when you're deploying large foundation models, running multiple models concurrently, or holding long-context KV-caches. If your workload doesn't need that much memory, you're paying for capacity that will sit unused.
Orin NX was designed for a generation of embedded workloads that predates the current wave of foundation models in robotics. It still works well for what it was designed for: multi-camera embedded vision, moderate inference workloads, classical robotics pipelines. But as robotics stacks move toward larger, more general-purpose models such as VLA models, multi-modal perception, and on-device planning, the constraint is typically not raw compute. It's memory: how much RAM the module has, and how fast the memory bandwidth can feed the compute.
We see this ceiling hit in almost every humanoid project that tries to push beyond scripted behaviors. The compute is often "enough on paper," but the memory budget forces model compression, quantization, or offloading decisions that erode the very capabilities the customer wanted to deploy in the first place.
T5000 solves the memory and compute question convincingly. The problem is cost, both in per-module price and in the surrounding platform: cooling, power delivery, integration effort. For a research-grade humanoid or a flagship demonstration platform, that cost is justifiable. For a fleet of service robots, warehouse humanoids, or smart-space sensor arrays, it isn't.
Multiple customer conversations we've had go the same way: "we need this level of capability, but not at T5000 price and thermal footprint." Until now, the answer has been to over-spec with T5000 or under-spec with Orin NX and live with the compromises. Neither is ideal.
T2000 and T3000 give you the same Blackwell GPU architecture and Neoverse CPU family as T5000, with proportionally scaled compute and RAM. The trade-off is straightforward: you accept a smaller memory ceiling — 16 GB on T2000, 32 GB on T3000 — that constrains model size and multi-model concurrency. In exchange, you get materially lower cost, less than half the thermal footprint, and a form factor that actually fits into humanoid and mobile robotics platforms without dominating the power budget.
For a lot of robotics workloads, that's a very reasonable trade. Most VLA models targeting on-robot deployment are being distilled and optimized to fit in memory budgets the mid-tier can comfortably support. Multi-modal perception stacks running on-device typically don't need T5000-class memory unless they're also doing extensive on-device planning in parallel. And crucially, because T3000 shares T5000's 273 GB/s memory bandwidth, throughput on many workloads scales much more gracefully than the raw compute numbers alone would suggest.
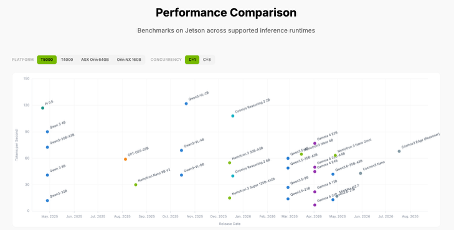
Here we find for comparison the T5000 with Tokens/s on different models:
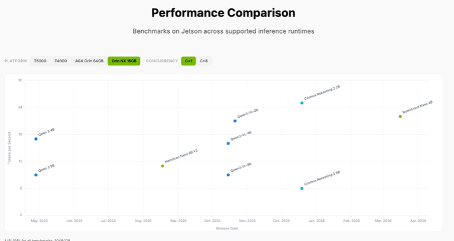
In comparison the Jetson Orin NX:
Source: https://www.jetson-ai-lab.com/models/
The key question for each project is simple: does the model need T5000-class memory, or does it fit comfortably in 32 GB? For most of the projects we see today, the answer is the second. That will shift over time as models grow, which is exactly why the lineup is structured this way.
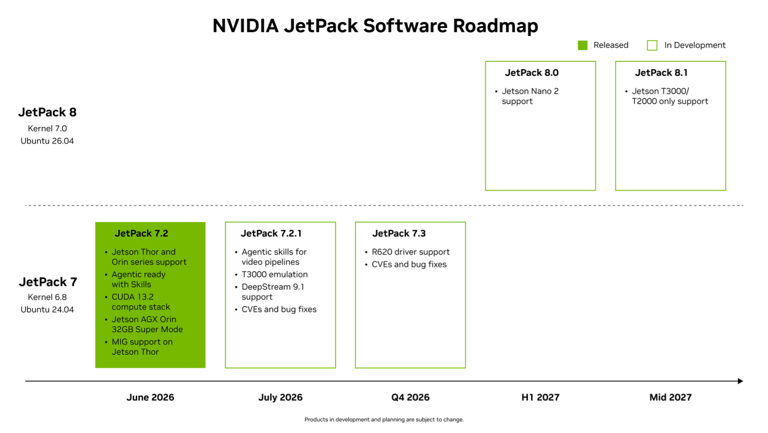
Everything sits on the NVIDIA JetPack stack, which is designed to streamline development across the family and points toward strong software portability: similar BSP line, same driver ecosystem, same acceleration APIs. That said, nothing has been officially confirmed yet on cross-generation compatibility between Orin-generation modules and the Thor family. We're carefully watching how much of a customer's stack will actually port cleanly between modules, especially when moving from an Orin-generation deployment to next-generation platforms. NVIDIA's public Jetson roadmap is where the concrete answers will surface first.
Source: https://developer.nvidia.com/embedded/develop/roadmap
Our approach for customers is straightforward: we design our platforms and integration layers with module portability in mind, so that when the compatibility questions get answered in one direction or another, projects aren't locked into a single module by design decisions made too early. This is the same reasoning we applied when building the driver-integration layer for our Thorium 16x GMSL2 platform. The specific chips change; the abstraction should not.
Based on the customer conversations we've had so far, the clear fits are:
Humanoid robotics at scale. Not flagship demonstrator platforms, but the tier below: service robots, warehouse humanoids, industrial robots moving toward multi-modal perception and on-device VLA. The memory budget is enough for current-generation compressed VLA models. The cost budget allows for the higher unit counts these applications actually need.
Smart spaces with on-device inference. Retail analytics, industrial safety monitoring, smart building systems: anywhere you want multi-camera edge AI with modern models but can't justify T5000 per node. The mid-tier compute-to-cost ratio matches this class of application much better than the flagship does.
Autonomous mobile robots (AMRs) in warehousing and logistics, where the workload is a mix of perception, localization, and planning, and where the cost of the compute module directly shapes platform economics.
Advanced multi-camera edge AI setups where the platform needs to run larger models than Orin NX comfortably fits, but doesn't require the full T5000 compute-and-memory envelope.
T2000 and T3000 are, in our view, the modules that will let modern robotics and smart-spaces workloads move from prototype to fleet over the 12 to 24 months following their launch. The modules themselves are expected in Q1 2027. T5000 will remain the right answer for high-end platforms and research systems that need every megabyte of memory and every TOPS of compute. But most projects don't need T5000. They needed a mid-tier module that didn't exist until now.
We're currently designing our first T2000/T3000-based platforms in parallel with the module launch. If you're sizing a robotics or smart-spaces project for that window or later and want to talk through where T2000, T3000, or T5000 will fit your specific workload, get in touch.